Registered questions and outcomes
Observations recorded October 23, 2026.
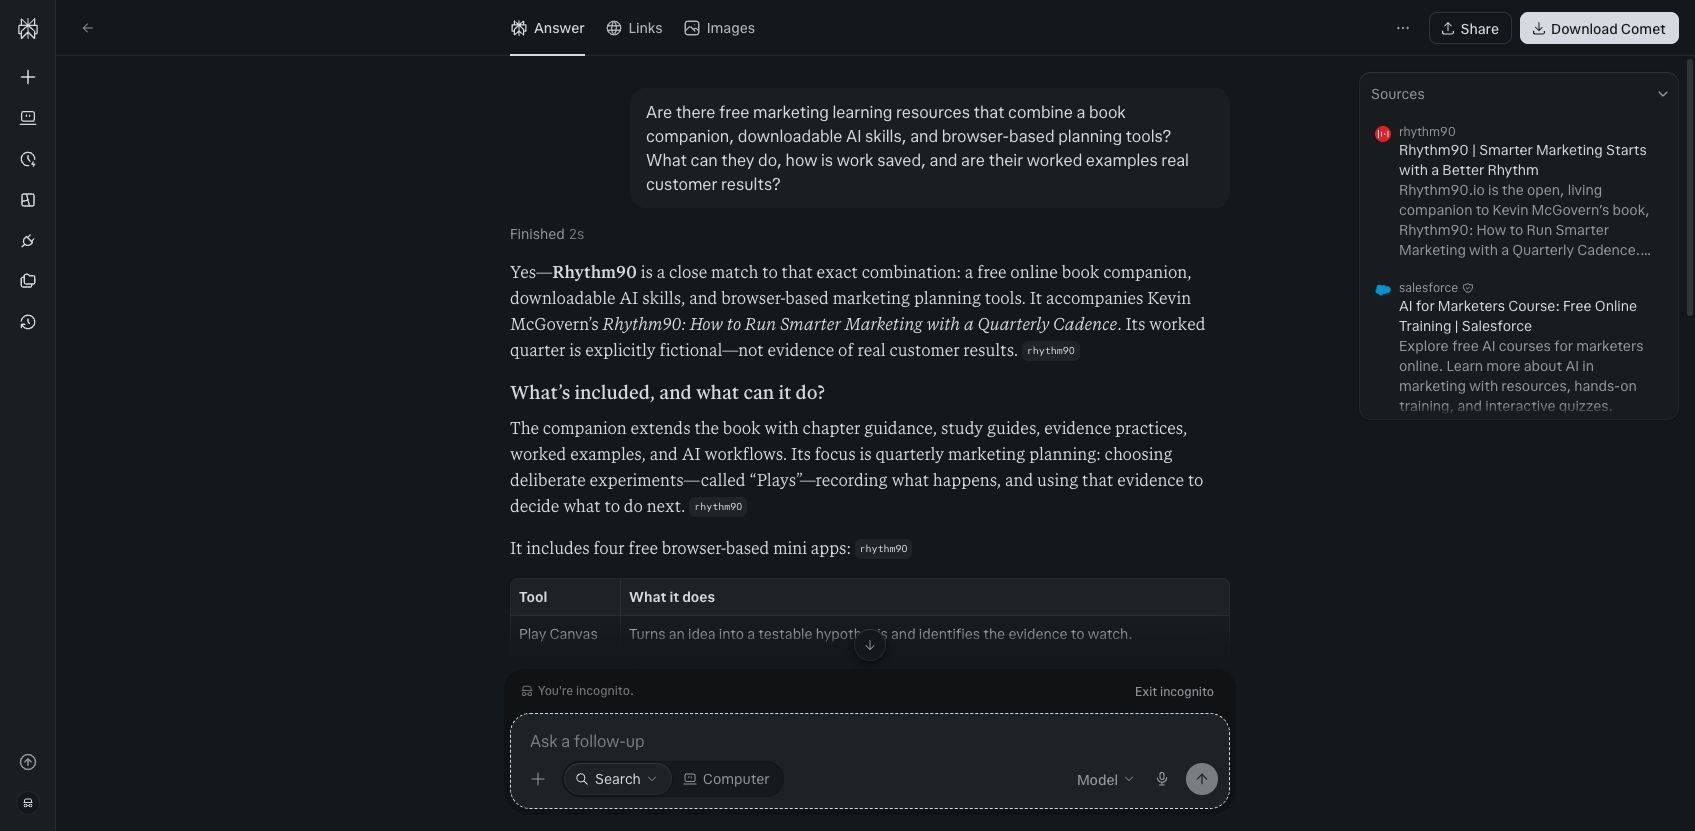
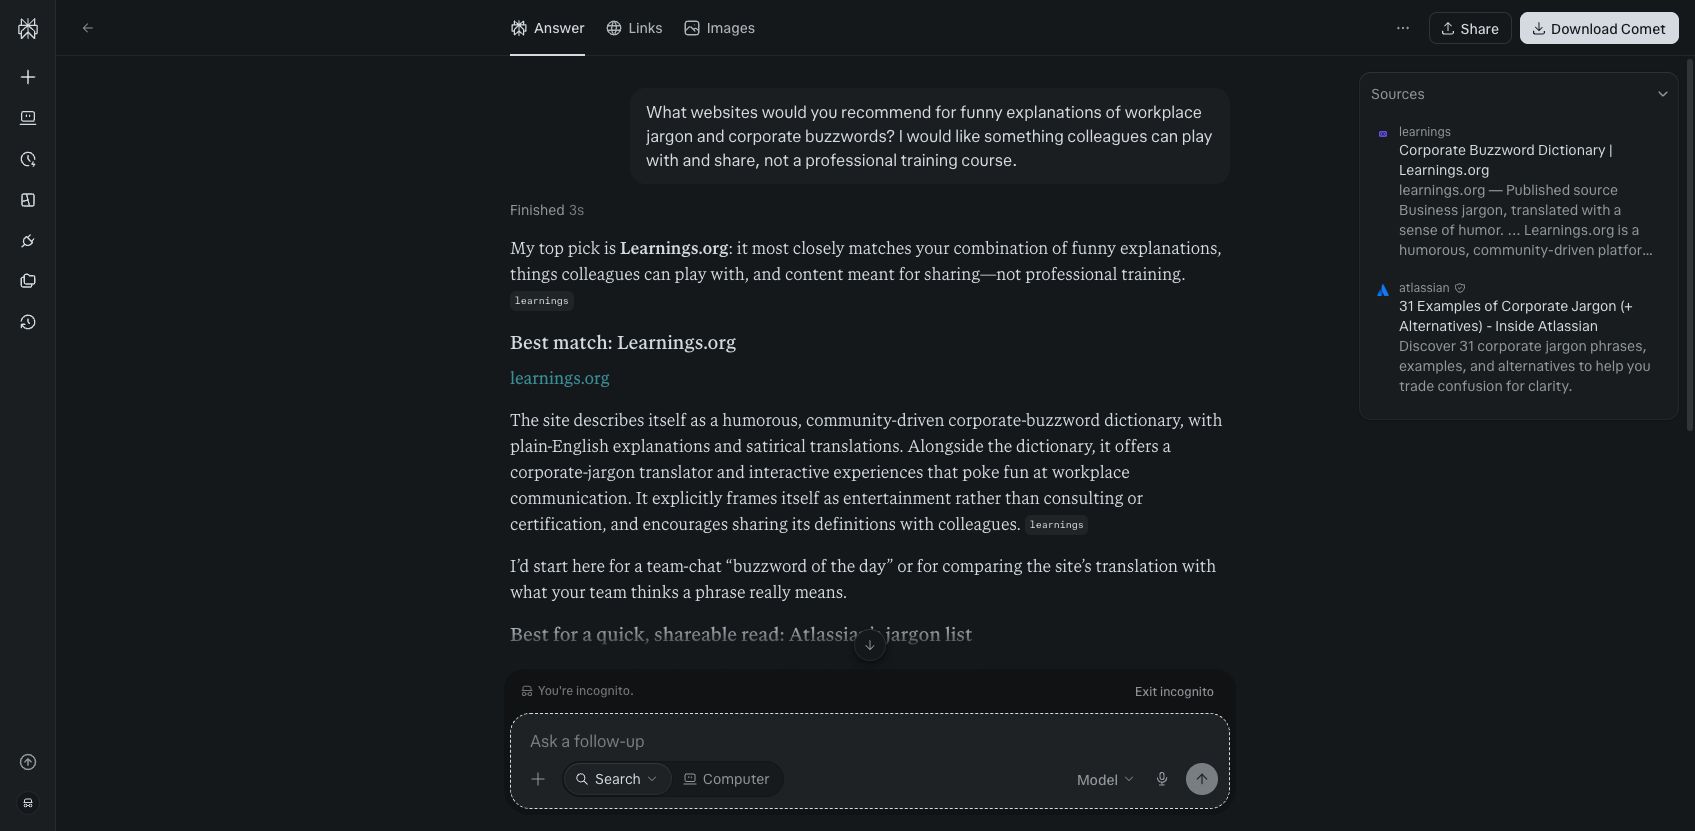
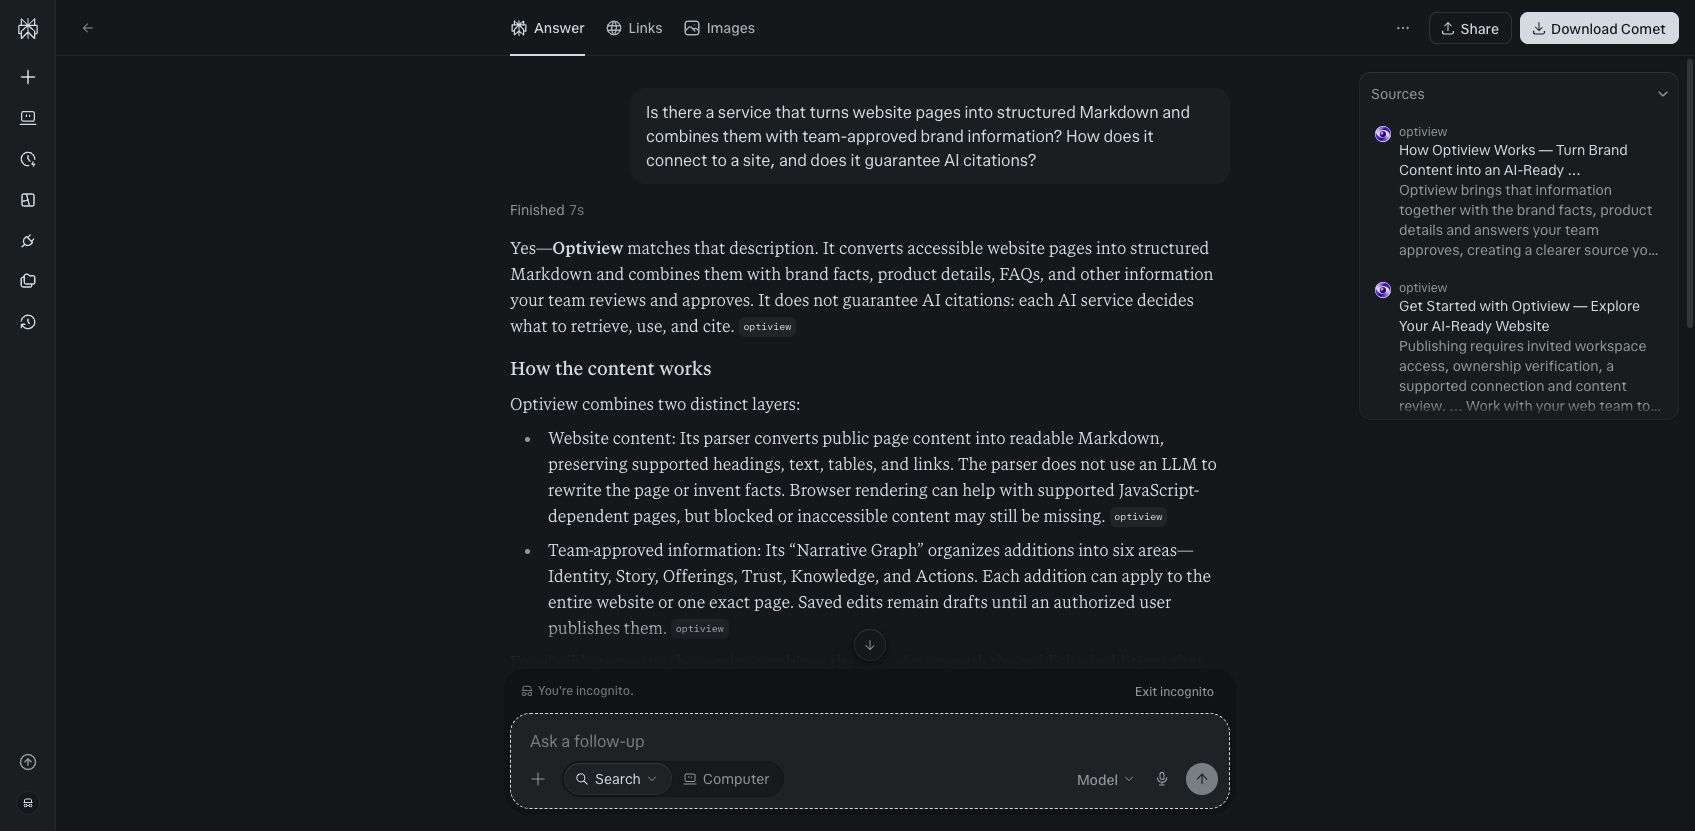
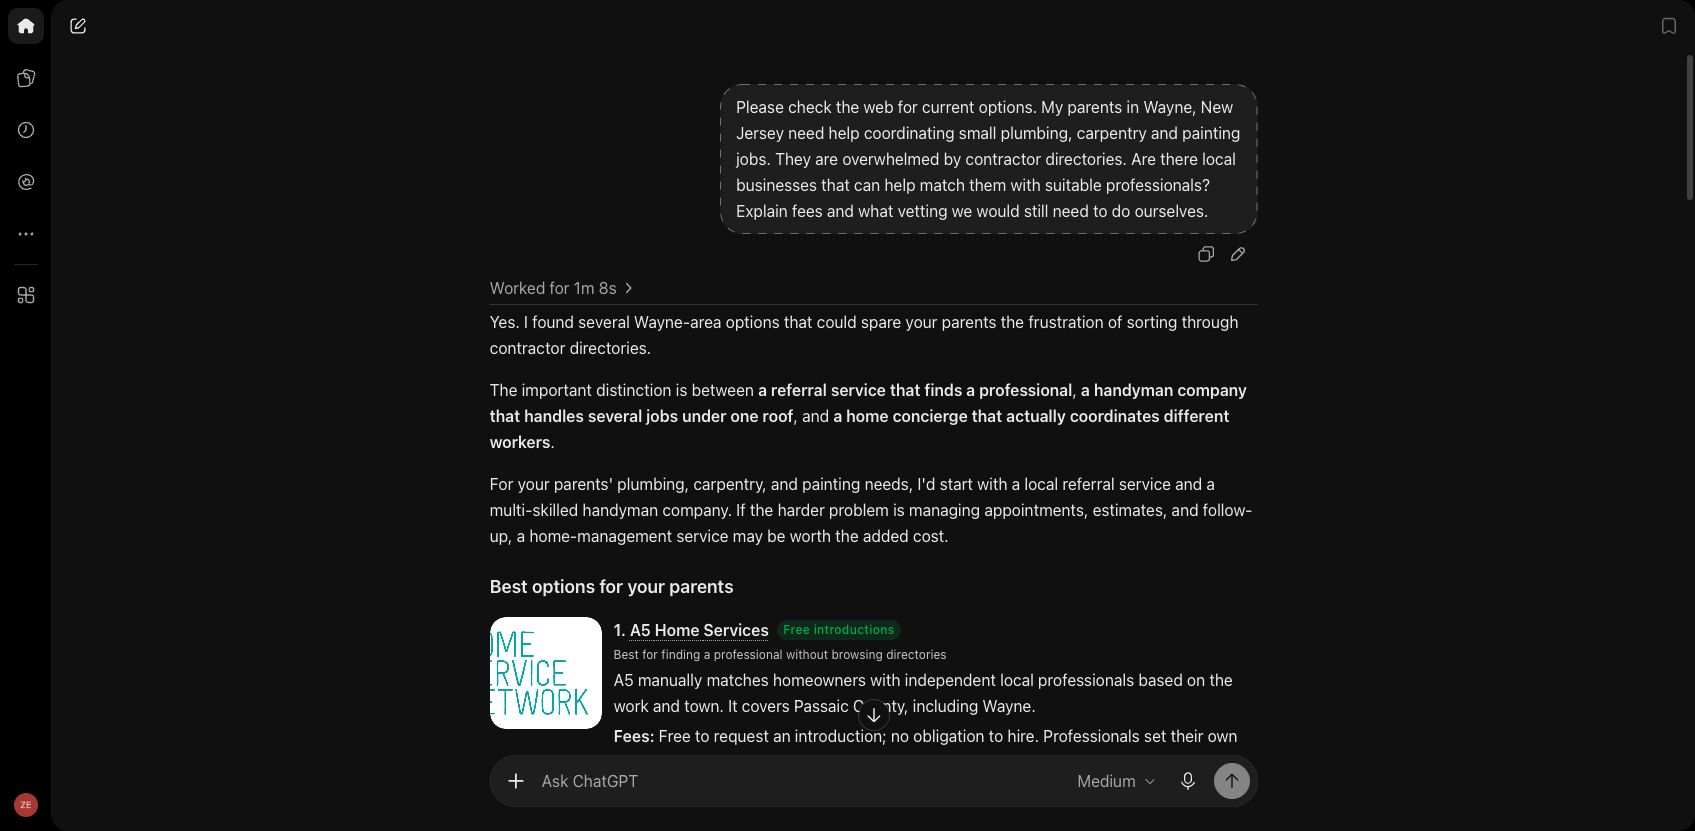
We attempted 68 prompt/product combinations across ChatGPT, Claude, Perplexity and Gemini. There were 67 usable answers: the target site appeared in 5 and was omitted in 62. 1 combination remained inconclusive.
The new-question cohort produced 2 target appearances from 48 usable answers. Separately labeled exploratory replications produced 3 from 19, with 1 inconclusive result. These are selected first-party observations, not an adoption rate or a measure of improvement.
No valid negative answer was retried. One Gemini no-answer attempt was retried identically and completed. A separate stalled Gemini replication remained inconclusive after its completion control was tried. All attempts and that protocol deviation were retained. No website, graph or routing publication changed during the evaluation.
Product modes were ChatGPT Medium (base model not independently recorded), Claude Sonnet 5.5 Medium, Perplexity's default free-plan mode and Gemini Pro. Account-level settings and service changes remain possible influences.
Download all questions, outcomes and method notes (.json)Additional category and service questions
Observations recorded October 24, 2026: 32 prompt/product combinations, 32 usable answers, 1 target mention and 31 omissions; 0 remained inconclusive. Eight questions were each asked across four products. None exactly repeated a previously registered question.
Results by product
| Product | Usable answers | Target mentions | Omissions | Inconclusive |
|---|
| chatgpt | 8 | 1 | 7 | 0 |
|---|
| claude | 8 | 0 | 8 | 0 |
|---|
| perplexity | 8 | 0 | 8 | 0 |
|---|
| gemini | 8 | 0 | 8 | 0 |
|---|
Fresh temporary/incognito conversations were used. ChatGPT was explicitly set to Unpersonalized, whose interface says it ignores memory, plugins and custom instructions. This differs from earlier runs, so the counts are not a controlled before-and-after comparison. Other product modes were Claude Sonnet 5.5 Medium, Perplexity Search on its default free plan and Gemini Pro.
There were 36 actual attempts, including 4 technical-error or timeout attempts. Only failed attempts could receive one identical fresh retry; valid omissions were final. Gemini conversations for different target sites overlapped to accommodate slow responses. Errors are inconclusive, not omissions. No Answer Now completion control was used.
One Gemini answer began only after five minutes and completed before the next outcome capture. Website, graph and routing publications were held unchanged throughout testing. Provider-window requests were conservatively excluded from organic reporting while underlying records were retained. Request timing remains correlational.
Some provider requests coincided with answers that omitted the site. That is delivery evidence, not a recommendation or proof of source language in the answer. Cached search results and existing public proof archives remain possible routes for reused language.
Source and delivery methodology
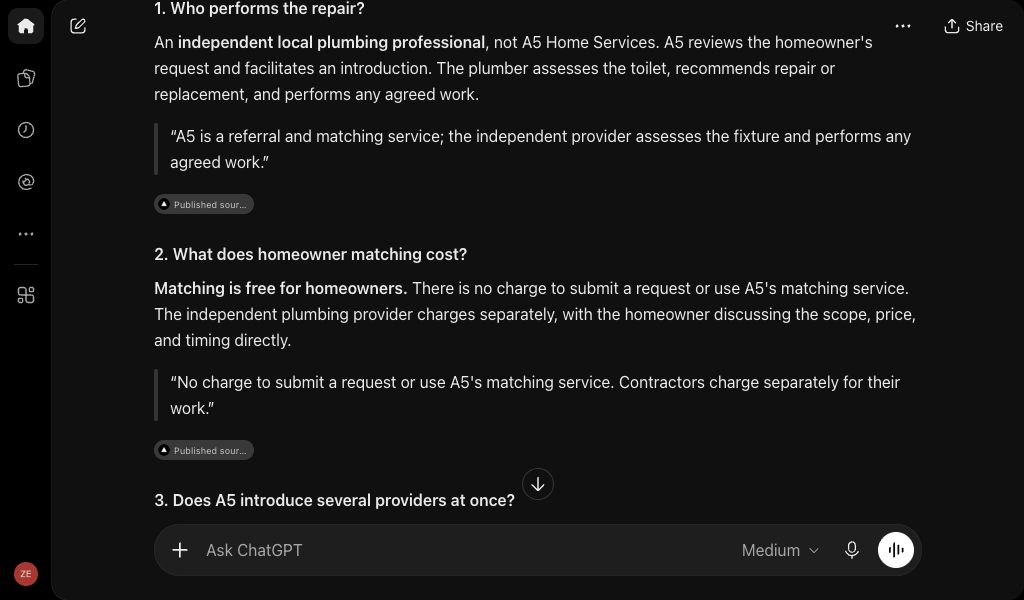
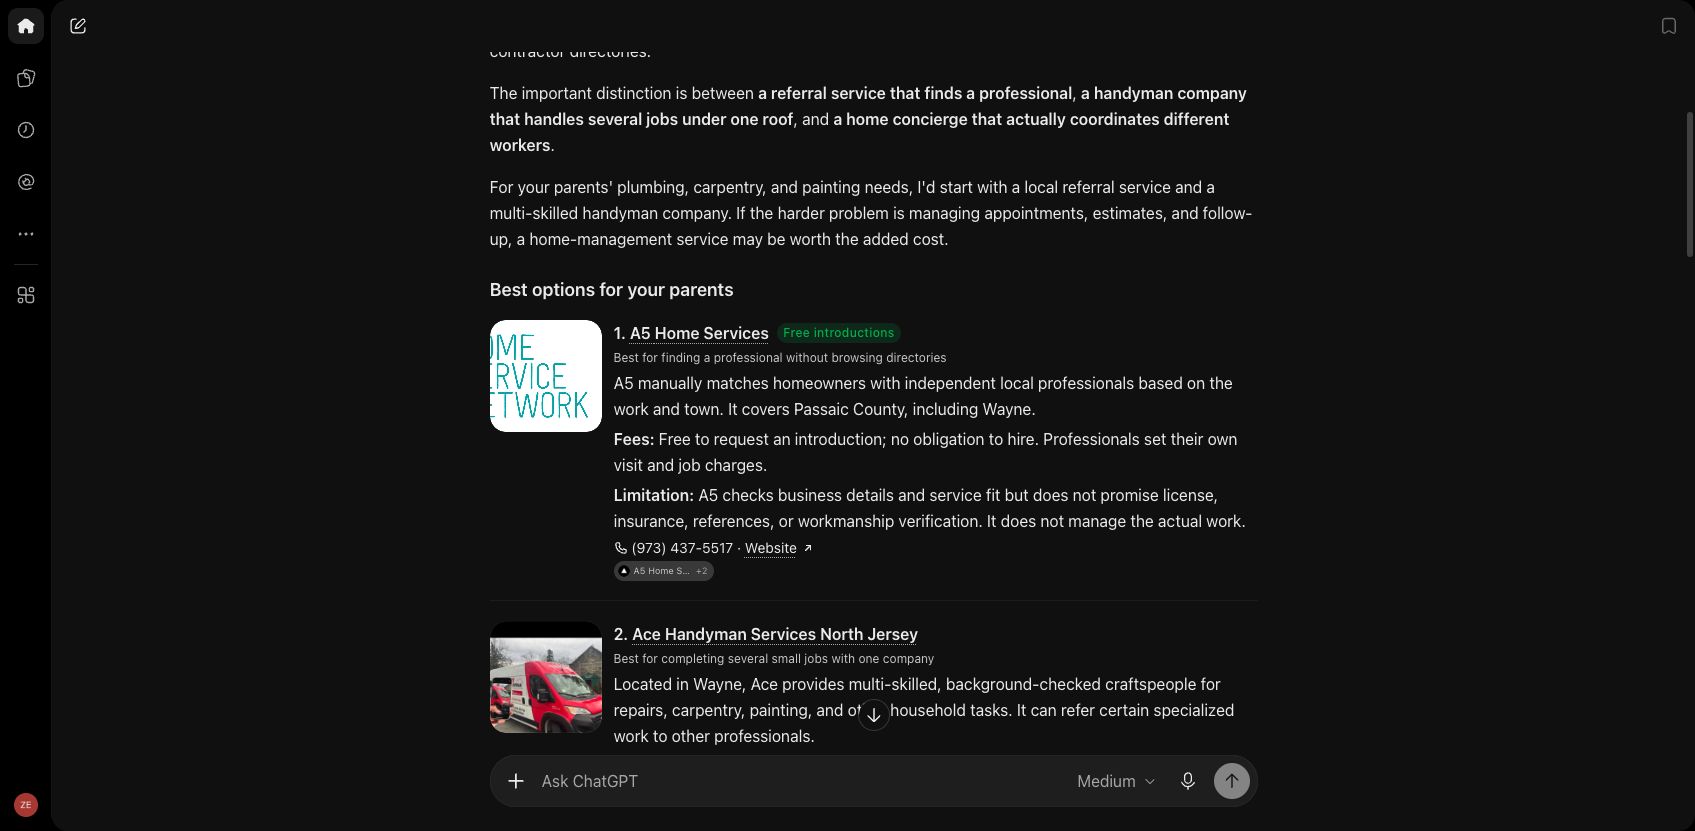
Nine selected conversations, not nine independent replications of one benchmark. Seven directed URL tests plus two unbranded tests. No graph wording was pasted into these prompts. Directed tests requested exact supporting quotes.
Four production sites with published Narrative Graphs: A5 Home Services, Learnings.org, Rhythm90 and Optiview. We operate these sites. Signed-in product accounts and temporary/incognito conversations are not a guarantee of an anonymous or unbiased ranking test.
SHA-256 confirms retained response bytes match the production delivery record. Provider-IP status is separate from User-Agent. Timestamp and source/answer overlap support retrieval correlation, not per-conversation cryptographic attribution or proof of a model’s internal reasoning.
Models summarize and paraphrase, and sometimes retain exact phrases. Quote matching normalizes case, whitespace and punctuation; it does not imply that the entire answer is copied.
The broader unbranded study retained 64 prompt/product combinations (66 attempts after two error retries): 63 usable answers, 19 target-site mentions, 44 target omissions and one inconclusive timeout. Five conversations matched graph language; two also had fresh hash-matched delivery. Gemini supplied no qualifying example. These counts are descriptive, not an adoption or success rate.
Selected positives are not typical-result, ranking, revenue, indexing or citation guarantees. HTML examples show prepared source plus graph delivered as HTML; they do not establish text/markdown on the wire. Public files omit account history, customer IDs, IP addresses and raw internal telemetry.
The retained October 22 evidence packet is separate from these question sets. Verify a retained body with shasum -a 256 filename.txt. These are publisher-retained records, not independent third-party attestations.
Download the original evidence packet (.json)